It allows me to have an idea of how long a book will take me to read. It also allows me to determine over time if I’m getting slower or faster reading books by using a website like How Long to Read. While the website says that reading a book such as Liu Cixin’s Death’s End should take 10h to read to the average reader at 300 WPM, it took me more than 20h to read it, which means I’m a very slow reader and that I read at less than 150 WPM.
The benefit of knowing how long a book will take me to read is that I can decide if I want to actually spend that time finishing the book or not. When a book is good, this question is not considered, but when it is bad, it is important to decide whether spending more time is a worthwhile use of my time.
To find questions, I will look at the notes I have taken in the past and search for question marks. I answer those questions as a way to stimulate my brain to think about questions I may rarely have the time to answer.
To find problems, I will look at my GitHub repositories. When I encounter a problem at work, I try to write it down so I can describe the issue in more details, which may hopefully help someone in a similar situation in the future.
Think about the question or problem for a little while, to see what I can come up with.
Write a list of items that I want to cover, this acts as my plan.
Describe the items in the list in more details.
Reference articles I’ve already written on the same topic.
Review the article using LLMs for grammatical mistakes and typos.
The approach I thought of to solve this problem was to write your change, run your tests (most likely using PHPUnit), then create a diff/patch of those changes and use this information to determine whether the lines that are part of the diff are covered. It should be relatively straightforward to automate the process of generating a patch from within a git repository as well as running PHPUnit within a project’s directory (generating a clover.xml report). With this information in hand, it would be possible for a script to compute what is and isn’t covered by tests in the changes that you are about to commit.
I wrote PHP Code Coverage Verifier which takes care of reading the PHPUnit output (a clover.xml file) and a generated patch file and produce a report of the lines that are and aren’t covered.
An example of the script output is as follow:
php vendor/bin/php-code-coverage-verifier verify my-clover.xml my-diff.patch
Using clover-xml file: my-clover.xml
With diff file: my-diff.patch

Covered:
controller/admin/stocks.php line 15 - 21
controller/admin/stocks.php line 91 - 97
controller/search.php line 26 - 32
controller/search.php line 376 - 384
model/user.php line 34 - 41
model/user.php line 44 - 51

Not covered:
controller/account.php line 39 - 45
controller/admin/stocks.php line 27 - 33
controller/search.php line 36 - 42
controller/search.php line 187 - 193
model/user.php line 533 - 540

Ignored:
application/composer.json

Coverage: 40 covered (56.338%), 31 not covered (43.662%)
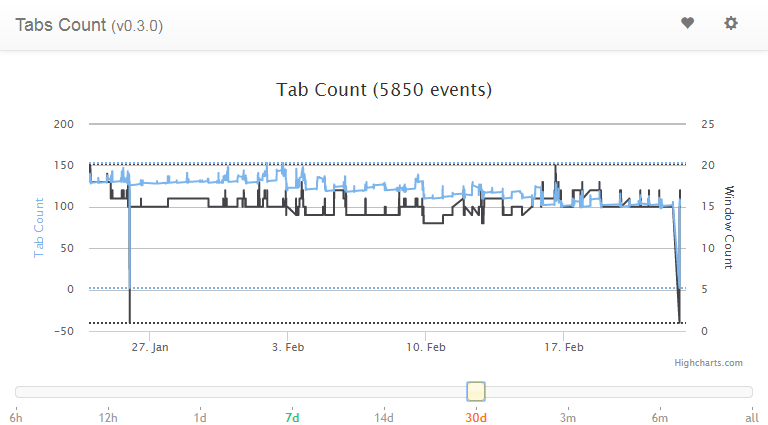
In January 2015 I wrote an extension for Chrome that allowed me to track how many tabs I had open. I called it the Chrome tabs count extension. It displays the number of currently opened tabs in the extension bar and when you click on the extension button itself, a chart is displayed with shows the tabs and windows count at each point a tab was opened/closed. This allows you to see the patterns of tabs creation/closing you have.
Such a tool will not help you reduce your tab count, but awareness is the first step toward reducing the number of tabs you have open at all times.
The second step is to taper (slowly reduce) the number of tabs you have open at all times. My strategy has been to reduce by 10 tabs each week the maximum number of tabs I had open. I started with over 160 tabs and I am now at 100 tabs after 6 weeks. I use the Loop Habit Tracker app to set up a daily reminder to make sure my tabs count is under the limit specified for this week and I try as hard as possible to finish the day with the number of tabs open below or at this limit.
I would separate the employees into multiple smaller companies, as large companies are difficult to wield. Furthermore, I think that it is useful for different companies to work on the same problem using different approaches, which is something I would promote. I see the need for a variety of positions:
(30%) Tooling and core technologies: Building tools that are used by other employees to make progress (visualization, compilation, hardware, database, network). (Bachelor/Master/PhD)
(25%) Applied research: Put the results of fundamental research into application in a variety of products. (Master/PhD)
(15%) Fundamental research: Work on scientific theories in order to improve our understanding of intelligence, learning, doing science, solving problems, programming, etc. (Master/PhD)
(15%) IT: Deal with infrastructure management and scaling. (Bachelor/Master/PhD)
(5%) Management: Ensuring that work is going in a specific direction and is not a random walk. (Bachelor/Master/PhD)
(5%) Data collector: Acquire data necessary for experiments done by fundamental researchers and applied research scientists. (Bachelor)
(5%) Administrative/HR/Facility management: Deal with business related tasks such as people management, facility management/maintenance, etc. (Bachelor)
I have taken a lot of pictures and I’d like to see where they were taken on a map. I also don’t want to have to upload those pictures to a server or download some software.
I’ve developed a simple tool called Photo geolocation which is a small client-side application. It uses leaflet to display the images on an OpenStreetMap map. The EXIF image metadata is extracted from the image by reading the image data using exif.js. From the EXIF image metadata we extract the GPS coordinates, which are then used to place a pin on the map at the appropriate location. It is possible to click on the pin to see what picture was taken at the provided location.
To use the tool, simply go to the website and drag and drop your images on the page. The images will be read by your browser, the EXIF image metadata read directly by the browser (nothing being sent to a server). The images with GPS coordinates will have a pin displayed on the map at the location they were taken, while those that do not have GPS coordinates will be simply logged to the browser console and not displayed.
As I am a developer, what is the most straightforward answer to this problem is to use a tool such as diff. When I write articles on my blog, I use Visual Studio Code which I have configured to save on window getting out of focus (or the current tab of the editor being changed). With this save event, I also create a git commit automatically with a very boring message “Automated save from VS Code.”. The point is not to have a fancy commit message, but to have a trace of when the changes where made. This allows me to offer to my visitors the ability to view the history of changes that were done to an article.
The downside to this approach is that it is not very easy to diff the article between two versions using the github web UI. It requires manually playing around the url, to provide the base and latest article SHA1 hash and to find the article in the list of files changed, which makes the experience rather painful and likely to lead nobody to do it.
Given that the git repository is available on my server where the blog is hosted, it would be possible for me to run a git diff command provided the last version seen by the visitor. This would allow me to present the changes that were done since the visitor last came. For instance, removal of sentences would be simply not displayed as removed since it is likely to be irrelevant to the visitor, however new sentences would be highlighted in green.
My approach is to write whatever I want to write about using whatever language I come up with first. Then I use a tool I’ve developed which I’ve called the vocabulary gradient. It is a very simple tool where you will generally copy and paste the article you’ve written and look at the result of the analysis. The tool uses a word frequency list as specified in the README.md. This list was built using the Project Gutenberg library, which makes the word frequency list a bit outdated.
The report generated by the tool presents the minimum, average, maximum and standard deviation of the index of the words used in the text you provided. Those numbers give you a rough overview of the difficulty of your text based on word frequency alone. The lower your average and maximum is, the simpler the article should be to understand An histogram is also generated, where the bins are based again on the index of the word in the frequency list. Finally, the provided text is rendered with each word index as a subscript. Words that are unknown are highlighted in yellow, while words for which the index is high are shaded with a darker shade of gray as their index increases.
With this information in hand, you can spot the words that have high word frequency indexes and try to replace them with lower index words.
I want my clients to share with me confidential data without revealing what the exact values are so that I can train machine learning models on this data.
I wrote a simple python package that uses pandas and scikit-learn to apply some simple transforms to the data. Some transforms that are applied to the dataset can change the distribution of the data, changing its statistical properties, while others preserve them but simply rescale the domain.
Given an anonymizer dataset using this tool, it is possible to do a preliminary data audit and possibly train machine learning models on the data to give a quick idea to clients whether their data looks promising or not without actually revealing the true numbers (except if desired).
The main concern with this approach is that most clients are not technical, and thus having them anonymize their data is generally not easy, if not impossible. Thus it means that such a tool is currently not applicable in the desired context.